 By
For decades, digital media operated under an unspoken evidentiary rule: while still photographs could be manipulated with enough time in Photoshop, realistic, dynamic moving video and synchronized voice audio were difficult to fabricate at scale. Video footage served as the bedrock of court evidence, news broadcasting, corporate governance, and personal trust.
The rise of generative artificial intelligence has dissolved that assumption.
Today, advanced machine learning architectures synthesize hyper-realistic video, clone human voices from three-second audio clips, and replace faces in live streams with sub-millisecond latencies. The technology behind this synthetic media revolution is known as deepfakes—a portmanteau of “deep learning” and “fake.”
Understanding deepfakes explained from the ground up requires looking beyond the hype. It demands an examination of the mathematical and algorithmic foundations that power synthetic media, how AI deepfake tools operate across audio and video, where legitimate enterprise applications exist, and how forensic detection techniques are evolving to defend digital truth.
1. What Are Deepfakes? The Mechanics of Synthetic Media
A deepfake is digital media—video, audio, or still imagery—manipulated or synthesized from scratch using deep artificial neural networks. Rather than relying on manual, frame-by-frame visual effects (VFX) editing, deepfake pipelines learn the underlying structural patterns of a target subject’s appearance, speech, and physical mannerisms from training data. Once trained, they map those behaviors onto novel source inputs.
TRADITIONAL CGI/VFX vs. DEEP LEARNING SYNTHETIC MEDIA

Traditional Visual Effects (CGI):
[3D Mesh Rigging] ──► [Manual Texture Painting] ──► [Keyframe Animation] ──► [Rendering Engine]
• Labor-intensive, requires specialized artists, deterministic mathematics.

AI Deepfake Synthesis:
[Training Data / Clips] ──► [Deep Neural Network] ──► [Latent Space Mapping] ──► [Automated Output]
• Unsupervised/self-supervised learning, probabilistic generation, scales in seconds.
To see how generative methods transform media creation, consider how traditional digital alteration contrasts with modern AI-generated video systems:
| Architectural Dimension | Traditional Video Editing (CGI / Manual) | First-Gen Deepfakes (2017–2021) | Modern Generative Media (Present) |
| Underlying Engine | Deterministic 3D modeling, compositing | Autoencoders (AEs) & Basic GANs | Latent Diffusion Models (LDMs) & DiTs |
| Data Requirements | Hundreds of manual animator hours | Thousands of matched face angles | Zero-shot / Few-shot (Single reference image/audio) |
| Execution Latency | Days to weeks per minute of footage | Hours of offline GPU model training | Real-time streaming generation / sub-second |
| Resolution & Realism | High, but limited by production budget | Prone to blurring, blinking anomalies | Physically accurate lighting, skin subsurface scattering |
| Audio Synchronization | Manual voice dubbing & audio splicing | Robotic, flat acoustic concatenations | Neural acoustic voice cloning with emotional cadence |
Synthetic media is not a single tool; it is an umbrella encompassing face swaps, voice cloning, full-body motion transfer, and text-to-video generation.
2. Under the Hood: The Four Core Deepfake Architectures
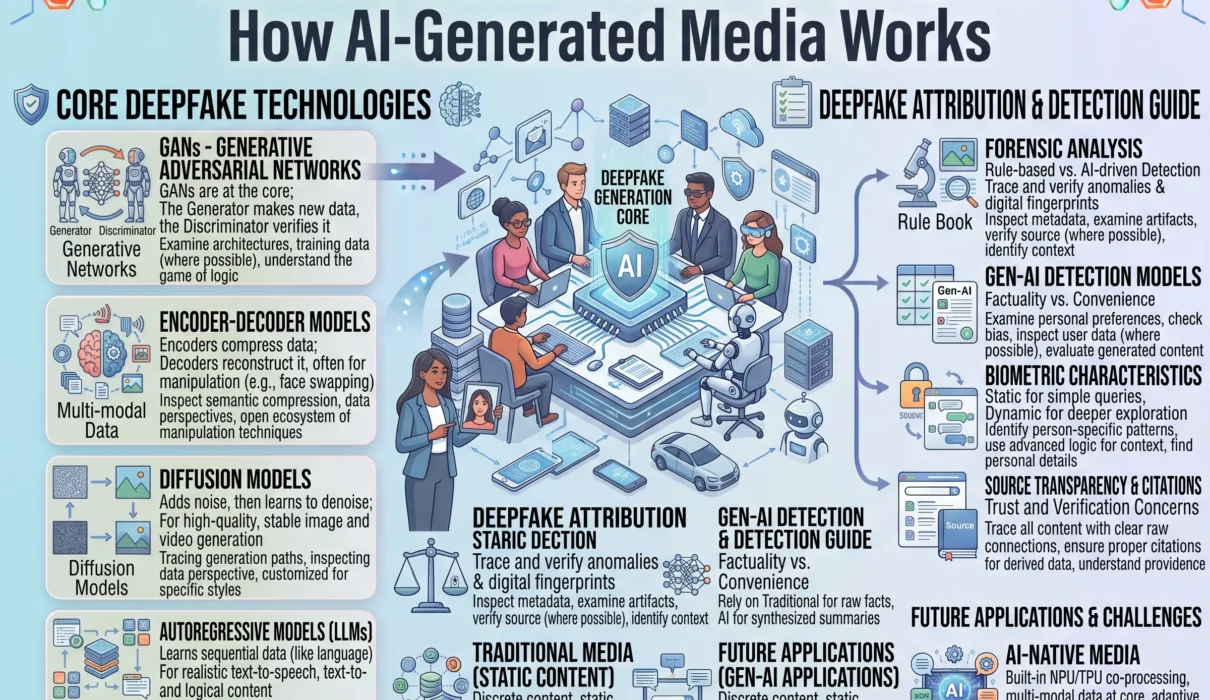
Behind every synthetic video or cloned voice track lies a deep neural network optimized for data reconstruction, adversarial competition, or iterative denoising. Four primary architectures drive modern deepfake technology:
┌────────────────────────────────────────────────────────────────────────┐
│                   THE GENERATIVE ARCHITECTURE SPECTRUM                 │
├────────────────────┬────────────────────┬──────────────────────────────┤
│ 1. AUTOENCODERS    │ 2. GANs            │ 3. DIFFUSION TRANSFORMERS    │
│    (Shared Encoder)│    (Generator vs.  │    (Spatiotemporal Noise     │
│    Learns shared   │     Discriminator) │     Reduction: Sora/Flux     │
│    latent faces    │    Adversarial     │     architectures)           │
│    for 1:1 swaps   │    refinement loop │    Physically coherent video │
├────────────────────┴────────────────────┴──────────────────────────────┤
│ 4. NEURAL AUDIO VOCODERS & LATENT ACOUSTIC DIFFUSION                   │
│    Transforms spectrograms into conditioned, high-fidelity waveforms   │
└────────────────────────────────────────────────────────────────────────┘
1. Autoencoders (The Original Face-Swap Pipeline)
The earliest deepfake algorithms (such as DeepFaceLab and FakeApp) were built on an autoencoder architecture. An autoencoder consists of two neural networks working in tandem: an Encoder that compresses a high-resolution face image into a compact, low-dimensional mathematical representation (latent space), and a Decoder that reconstructs the original face from that latent vector.
THE SHARED ENCODER / DUAL DECODER DEEPFAKE ENGINE

Training Phase:
Face A ──► [SHARED ENCODER] ──► [Latent Space Vector] ──► [DECODER A] ──► Reconstructed Face A
Face B ──► [SHARED ENCODER] ──► [Latent Space Vector] ──► [DECODER B] ──► Reconstructed Face B

Inference (Swap) Phase:
Target Face A ──► [SHARED ENCODER] ──► [Latent Vector] ──► [DECODER B] ──► Subject B with Face A's Pose
The mechanism relies on a clever constraint: both subjects share an identical Encoder, but use distinct, specialized Decoders.
- The shared encoder is forced to learn the universal structural features of human faces—eye spacing, head tilt, rotational yaw, and jawline contours—compressing both Person A and Person B into the same latent space coordinate system.
- Decoder A is trained only to reconstruct Person A from that latent space, while Decoder B is trained only to reconstruct Person B.
- To execute the deepfake, Person A’s face is fed into the shared encoder, but the resulting latent vector is passed into Decoder B.
- The output is Person B’s exact visual features, rendered with Person A’s dynamic expressions, eye direction, and head orientation.
2. Generative Adversarial Networks (GANs)
While autoencoders produce convincing face swaps, they often suffer from blurry boundaries and unnatural skin blending. Generative Adversarial Networks (GANs), introduced by Ian Goodfellow et al. in 2014, elevated synthetic fidelity by pitting two neural networks against one another in an iterative zero-sum game.
                     GENERATIVE ADVERSARIAL NETWORK (GAN)

  [Latent Noise Vector] ──► [GENERATOR NETWORK] ──► [Candidate Synthetic Image]
                                                           │
                                                           ▼
  [Authentic Target Media] ───────────────────────► [DISCRIMINATOR NETWORK]
                                                           │
                                                           ├─► Predicts: Real or Fake?
                                                           │
        ┌──────────────────────────────────────────────────┴────────────────────┐
        ▼                                                                       ▼
  [If Detected as Fake]                                                   [If Fooled]
  Backpropagation penalizes Generator;                                    Discriminator updates
  Generator adjusts weights to improve realism.                           weights to catch fraud.
- The Generator: Synthesizes candidate images from random noise or conditioned inputs, trying to emulate the statistical distribution of the training data.
- The Discriminator: Evaluates candidate images against authentic photographs, acting as an automated digital forensics examiner. It assigns a probability score indicating whether the image is real or artificially generated.
- Adversarial Training: As the discriminator gets better at identifying tiny imperfections (unnatural skin specularities, mismatched pupils), the generator adjusts its weights through backpropagation to bypass the discriminator’s filters. The networks train until the generator produces synthetic outputs mathematically indistinguishable from authentic training samples.
3. Diffusion Models and Diffusion Transformers (DiTs)
Modern state-of-the-art synthetic media systems (such as Stable Diffusion, FLUX, and OpenAI Sora) have largely superseded standalone GANs by moving to Diffusion Models and Diffusion Transformers (DiTs).
Where GANs can suffer from “mode collapse” (producing limited variations of an output) and training instability, diffusion models work through a continuous thermodynamic-inspired mathematical process:
- Forward Diffusion: The model takes a clean image or video frame and systematically destroys it by adding tiny increments of Gaussian noise over hundreds of discrete time steps until the input is pure static.
- Reverse Diffusion: A neural network learns the reverse transformation. Given an array of static conditioned by a text prompt, an audio track, or a source video, the model predicts and subtracts the exact noise pattern step by step, revealing a coherent image.
In Diffusion Transformers (DiTs), video is represented as three-dimensional spacetime patches (height, width, and time). This allows the model to process spatial features and temporal continuity simultaneously, virtually eliminating the jitter, flickering, and frame-to-frame warping that plagued earlier GAN video deepfakes.
4. Neural Voice Cloning (Latent Acoustic Synthesis)
Visual manipulation is only half the equation. Audio deepfakes clone human voices with frightening accuracy, requiring only seconds of clean target audio.
                       AUDIO DEEPFAKE SYNTHESIS PIPELINE

  [3-Second Target Audio Clip]
                │
                ▼
  ┌────────────────────────────────────────────────────────┐
  │ 1. NEURAL ACOUSTIC FEATURE EXTRACTOR                   │
  │    Extracts Speaker Embedding: Timbre, Pitch, Formants │
  └──────────────────────────┬─────────────────────────────┘
                             │
  [Arbitrary Text / Script]  │
                │            │
                ▼            ▼
  ┌────────────────────────────────────────────────────────┐
  │ 2. ACOUSTIC CONDITIONING MODEL                         │
  │    Synthesizes Mel-Spectrogram incorporating           │
  │    speaker timbre, prosody, and respiratory pauses     │
  └──────────────────────────┬─────────────────────────────┘
                             │
                             ▼
  ┌────────────────────────────────────────────────────────┐
  │ 3. NEURAL VOCODER (e.g., HiFi-GAN / WaveNet)           │
  │    Converts 2D Mel-Spectrogram into 48kHz audio wave   │
  └────────────────────────────────────────────────────────┘
- Speaker Embedding Extraction: A convolutional or attention-based network analyzes reference audio, extracting a mathematical “speaker embedding vector.” This vector encodes physiological vocal traits: vocal tract resonance, vocal fold thickness, pitch range, and accent.
- Acoustic Conditioning: A transformer model ingests arbitrary text or phonetic sequences and generates a visual representation of sound frequencies over time: a Mel-spectrogram. The speaker embedding is injected into the model’s attention layers, conditioning the spectrogram to match the target speaker’s unique vocal color.
- Neural Vocoding: A neural vocoder (such as HiFi-GAN or modern diffusion vocoders) converts the 2D Mel-spectrogram into raw 1D acoustic audio pressure waves (48kHz audio), synthesizing natural cadence, breath intakes, and subtle vocal fry.
3. Legitimate Applications: Where Synthetic Media Delivers Real Value
While deepfakes are frequently discussed through the lens of fraud and exploitation, synthetic media is simultaneously emerging as a multi-billion-dollar creative and operational technology.
┌────────────────────────────────────────────────────────────────────────┐
│               ENTERPRISE USE CASES FOR SYNTHETIC MEDIA                 │
├─────────────────────┬──────────────────────────────────────────────────┤
│ Industry Domain     │ Commercial Implementation Mechanism              │
├─────────────────────┼──────────────────────────────────────────────────┤
│ Entertainment &     │ Automated multi-language voice dubbing with      │
│ Film Production     │ synchronized lip phoneme-viseme alignment.       │
├─────────────────────┼──────────────────────────────────────────────────┤
│ Accessibility &     │ Personalized synthetic voice restoration for ALS │
│ Assistive Tech      │ patients and vocally impaired individuals.       │
├─────────────────────┼──────────────────────────────────────────────────┤
│ Enterprise Training │ Real-time localized video training modules       │
│ & Education         │ generated from centralized corporate documentation.│
├─────────────────────┼──────────────────────────────────────────────────┤
│ Gaming & Virtual    │ Generative non-player character (NPC) dialogues  │
│ Interactive Worlds  │ with dynamic real-time facial expressions.       │
└─────────────────────┴──────────────────────────────────────────────────┘
1. Film Production, De-Aging, and Posthumous Performance
Traditional visual effects studios spend millions of dollars manually de-aging actors or creating synthetic digital doubles for stunt scenes. Neural rendering tools allow directors to apply age adjustments, alter lighting across an actor’s face post-wrap, or digitally reconstruct historic figures with archival fidelity, cutting production timelines from months to days.
2. Hyper-Realistic Multi-Language Dubbing
Historically, translating a film or corporate lecture meant replacing the original audio with a foreign-language voice actor, creating a jarring disconnect between the spoken words and the actor’s moving mouth.
AI-driven video synthesis aligns visual visemes (mouth shapes) to foreign phonemes (spoken sounds):
- When an English-speaking CEO’s video is translated into Japanese, German, or Arabic, neural models synthesize the translated audio in the CEO’s cloned voice.
- The system modifies the speaker’s lips and jaw movements in the video frame, making it appear as though the speaker is natively fluent in the target language.
3. Assistive Healthcare and Vocal Reconstruction
For patients diagnosed with degenerative neurological disorders like Amyotrophic Lateral Sclerosis (ALS) or individuals undergoing throat surgery, synthetic voice cloning provides life-changing medical utility:
- Patients record phrases while their voice remains intact.
- Neural models train a custom voice synthesis profile.
- When the patient loses physical speech, eye-tracking hardware coupled with the voice model allows them to speak through assistive tablets with their original vocal identity, preserving human connection.
4. Scalable Corporate Communication and Education
Global organizations use synthetic avatars (platforms like Synthesia, HeyGen, or Colossyan) to produce standardized training materials, customer support explainers, and educational videos from text scripts.
When corporate safety protocols or legal disclosures change, teams update the text prompt, generating an updated, multi-lingual instructional video without renting studio space, setting up camera gear, or hiring video presenters.
4. The Dark Side: Malicious Risks and Weaponization Vectors
The democratization of open-source deepfake models has lowered the barrier to entry for malicious actors. Capabilities that once required high-end compute clusters can now run on consumer GPUs or through web interfaces, creating distinct categories of operational, societal, and political risk.
                     THE DEEPFAKE THREAT MATRIX

     Disinformation & Geopolitics               Financial Fraud & CEO Cloning
    ┌───────────────────────────┐              ┌───────────────────────────┐
    │ Fabricated leader speech  │              │ Synthetic executive audio │
    │ triggers civil unrest or  │ ───────────► │ authorizes fraudulent wire│
    │ market flash crashes.     │              │ transfers ($25M+ losses). │
    └───────────────────────────┘              └───────────────────────────┘
                                 │
                                 ▼
                     Biometric Authentication Bypass
                    ┌───────────────────────────┐
                    │ Real-time virtual cameras │
                    │ bypass identity KYC and   │
                    │ video banking onboarding. │
                    └───────────────────────────┘
1. Financial Fraud and Business Email Compromise (BEC)
Deepfake audio is now a frontline attack vector in corporate fraud.
Adversaries harvest clips of corporate executives from earnings calls, YouTube interviews, and public keynotes to clone their voices. The attacker calls a mid-level financial controller, mimicking the CFO’s vocal cadence, tone, and urgency, and instructs them to execute an emergency wire transfer to an offshore account.
In a notable high-profile incident in Hong Kong, a finance worker was tricked into paying out $25 million after attending a video conference call populated entirely by deepfake recreations of the company’s chief financial officer and colleagues.
2. Biometric KYC and Facial Recognition Bypass
Financial institutions, government agencies, and digital identity platforms rely on automated “Know Your Customer” (KYC) identity verification: users upload a driver’s license and record a selfie video moving their head to prove “liveness.”
Attackers feed synthetic media directly into software virtual camera drivers (such as OBS Studio):
- Generative models synthesize a digital face matching the identity documents.
- The system accurately executes requested challenge-response actions—blinking, smiling, turning left, and nodding—tricking automated biometric systems into approving fraudulent loans and accounts.
3. Non-Consensual Synthetic Imagery (NCII)
The most widespread use of deepfakes involves non-consensual synthetic sexual imagery. Deepfake software is routinely weaponized to harass private citizens, journalists, and public figures by superimposing their likenesses onto explicit material. This creates severe psychological trauma, defamation, and reputational harm, prompting global legislative crackdowns and criminalization statutes.
4. Electoral Interference and Societal Epistemic Chaos
During volatile election cycles, an AI-generated video showing a candidate withdrawing from a race, admitting to a crime, or making an offensive statement can spread virally hours before polls open.
Even if forensic specialists debunk the video within twenty-four hours, the initial impression can influence voter turnout.
Beyond the impact of real fakes lies an equally dangerous psychological phenomenon: The Liar’s Dividend. As the public becomes widely aware that video can be generated out of thin air, bad actors caught on legitimate, authentic video can simply claim the evidence is an “AI deepfake,” undermining objective reality and public trust.
5. How to Detect Deepfakes: Forensic and Technical Approaches
Detecting synthetic media has transformed into an adversarial arms race. As detection algorithms identify a specific synthetic artifact, model creators refine their training losses to eliminate the flaw.
Modern deepfake detection operates across three technical layers: Biological/Physical Anomalies, Signal-Level Machine Learning Forensics, and Cryptographic Content Provenance.
┌────────────────────────────────────────────────────────────────────────┐
│                   DEEPFAKE DETECTION PARADIGMS                         │
├─────────────────────┬──────────────────────────────────────────────────┤
│ Detection Tier      │ What the Technology Inspects                     │
├─────────────────────┼──────────────────────────────────────────────────┤
│ 1. Biological &     │ Subdermal pulse (rPPG), corneal light reflections│
│    Physical Signals │ audio-visual phoneme/viseme timing mismatches.   │
├─────────────────────┼──────────────────────────────────────────────────┤
│ 2. Deep Signal &    │ High-frequency Fourier spectrum artifacts, pixel │
│    Pixel Forensics  │ compression boundaries, GAN model fingerprints.  │
├─────────────────────┼──────────────────────────────────────────────────┤
│ 3. Cryptographic    │ Cryptographic manifests (C2PA), hardware sensor  │
│    Provenance       │ digital signatures, verifiable edit histories.   │
└─────────────────────┴──────────────────────────────────────────────────┘
1. Biological and Physical Inconsistency Analysis
Early generative models struggled with biological processes. While models have improved, physical inconsistencies remain a primary detection vector:
- Remote Photoplethysmography (rPPG): When a living human heart beats, blood pumps through facial capillaries, causing microscopic, periodic skin color shifts imperceptible to the human eye. Machine learning models analyze video frames over time to detect this rhythmic cardiovascular pulse. Synthetic deepfake faces lack this biological heartbeat signature, failing rPPG tests.
- Corneal Specular Reflection Consistency: In real-world video, light sources in an environment reflect across both eyeballs in geometrically consistent patterns. Deepfake models often render the left and right eye independently or fail to model accurate 3D scene physics, producing mismatched reflections, inconsistent catchlights, or irregular pupil shapes.
- Phoneme-Viseme Cross-Modal Synchronization: Forensic audio-visual models cross-reference the exact acoustic frequency profile against visual lip geometry. Producing sounds like “B”, “M”, or “P” (bilabial consonants) requires human lips to touch completely. If the audio waveform contains an “M” sound while the visual mouth remains slightly parted, the media is flagged as synthetic.
                     BIOLOGICAL SIGNAL DETECTION: rPPG

  Authentic Human Video Frame Stream:
  [Frame 1] ──► [Frame 30] ──► [Frame 60] ──► [Frame 90]
      │             │              │             │
      └─────────────┴──────────────┴─────────────┴──► Periodic Pulse Extracted: 72 BPM

  AI-Synthesized Deepfake Stream:
  [Frame 1] ──► [Frame 30] ──► [Frame 60] ──► [Frame 90]
      │             │              │             │
      └─────────────┴──────────────┴─────────────┴──► Erratic, Flatline Noise (Zero Pulse)
2. Frequency Domain and Pixel-Level Forensics
Generative models do not paint images like human artists; they compute pixel arrays through convolutional upsampling or discrete cosine transformations. These mathematical operations leave subtle, imperceptible statistical markers:
- Fourier Transform Analysis: Transforming a video frame from the spatial domain to the frequency domain (via Fast Fourier Transform) exposes regular, grid-like artifact patterns introduced by convolutional upsampling layers, known as “GAN fingerprints”.
- Spatiotemporal Continuity: Capsule Networks and hybrid Vision Transformers evaluate relationships between video frames. Synthetic video often exhibits micro-jitters, sudden shifts in facial boundary blurriness, or temporal lag between facial movements and neck muscles across sequential frames.
3. The Shift to Cryptographic Provenance (C2PA)
Relying solely on post-hoc forensic detection is an uphill battle. As diffusion models improve, forensic artifacts disappear.
The industry is pivoting toward Content Provenance—verifying authenticity at the point of capture rather than attempting to detect fakes retroactively.
                      THE C2PA PROVENANCE CHAIN

  [Camera Hardware Sensor]
             │
             ├─ Cryptographically signs image capture with hardware-backed key
             ├─ Embeds GPS coordinates, timestamp, camera lens parameters
             │
             ▼
  [Cryptographic Metadata Manifest (Content Credentials / C2PA Standard)]
             │
             ├─ Tracks Photoshop color grading: Adds cryptographically signed edit hash
             ├─ Tracks AI In-Painting tool: Appends generative modification manifest
             │
             ▼
  [Consumer Viewport (Web / Social)]
  Clicking "CR" badge displays tamper-evident audit trail from sensor to screen.
Spearheaded by the Coalition for Content Provenance and Authenticity (C2PA)—a cross-industry consortium including Adobe, Microsoft, Intel, and the BBC—provenance standards embed cryptographic metadata directly into media files:
- When an image or video is captured by a supported camera or smartphone, the device’s secure enclave signs the file with a digital certificate.
- As the media is edited, certified software appends a cryptographically verified ledger (“Content Credentials”) documenting the edits.
- If an AI model alters the pixels, the manifest logs that generative tools were used.
- If an attacker strips the metadata or alters the underlying pixels without signing the change, the cryptographic hash breaks, alerting platforms that the file’s provenance is untrusted.
6. How to Spot Deepfakes: A Practical Visual Checklist
While advanced detection tools require forensic software, everyday consumers can spot many synthetic videos by looking for telltale rendering flaws:
┌────────────────────────────────────────────────────────────────────────┐
│                   HUMAN DEEPFAKE INSPECTION GUIDE                      │
├─────────────────────┬──────────────────────────────────────────────────┤
│ Visual Focus Zone   │ Subtle Artifacts to Look For                     │
├─────────────────────┼──────────────────────────────────────────────────┤
│ Eyes & Gaze         │ • Unnatural or absent blinking patterns          │
│                     │ • Mismatched specular reflections (catchlights)  │
│                     │ • Pupils that appear oblong or non-circular      │
├─────────────────────┼──────────────────────────────────────────────────┤
│ Mouth & Teeth       │ • Blurry, uniform white blocks instead of teeth  │
│                     │ • Lips that don't close on "B", "M", "P" sounds  │
│                     │ • Unnatural tongue movements during speech       │
├─────────────────────┼──────────────────────────────────────────────────┤
│ Edges & Lighting    │ • Blurring around jawlines, ears, and neck folds │
│                     │ • Lighting direction on the face that mismatches │
│                     │   shadows cast on surrounding shoulders/walls   │
├─────────────────────┼──────────────────────────────────────────────────┤
│ Audio & Breath      │ • Absence of natural breath intakes between lines│
│                     │ • Flat, metallic acoustics or sudden tone shifts │
│                     │ • Background noise that abruptly cuts out        │
└─────────────────────┴──────────────────────────────────────────────────┘
- Watch the Neck and Jawline: Face-swap models paste a new face over an existing head. Look for subtle blurring, pixel smearing, or skin-tone mismatches where the jawline meets the neck.
- Inspect Complex Geometries: AI struggles with intricate intersecting shapes. Look closely at hands, fingers, glasses frames, and jewelry (like dangling earrings). Deepfake models often warp earrings, blend glasses directly into cheekbones, or render unnatural numbers of fingers.
- Listen for Natural Breath Sounds: When humans speak, they pause to inhale, creating subtle acoustic breathing patterns. AI voice clones often deliver complex paragraphs in an unbroken, monotonic rhythm with zero respiratory pauses.
7. Comparative Technical Matrix: Generative Frameworks
To evaluate the engineering trade-offs between different deepfake synthesis technologies:
| Metric | Autoencoders (DeepFaceLab) | Generative Adversarial Networks (GANs) | Diffusion Transformers (DiTs) | Neural Voice Cloners (Acoustic) |
| Primary Media Output | 1:1 Video Face Swaps | High-res still faces, simple videos | Coherent, text-to-video scenes | 48kHz synthesized voice waveforms |
| Training Time | High (Days per specific subject) | Moderate to High (Prone to instability) | Massive (Warehouse-scale GPU clusters) | Low (Seconds to minutes fine-tuning) |
| Data Requirements | Thousands of matched face images | Tens of thousands of images | Hundreds of millions of video clips | 3 to 60 seconds of reference audio |
| Visual Artifacts | Blurry edges, low resolution | Facial warping, mode collapse | Long-range temporal physics drift | Metallic timbre, robotic prosody |
| Inference Hardware | Consumer GPUs (RTX 3080/4090) | Enterprise GPUs (A100/H100) | High-end Cloud Inference Racks | Standard Mobile NPU / Laptop CPU |
8. Strategic Defense: How Enterprises Must Respond
Organizations can no longer rely on voice verification or standard video calls as secure identity checks. Defending corporate infrastructure against synthetic media attacks requires a multi-layered security overhaul:
┌────────────────────────────────────────────────────────────────────────┐
│                   ENTERPRISE DEEPFAKE DEFENSE ROADMAP                  │
├─────────────────────┬──────────────────────────────────────────────────┤
│ Defense Layer       │ Tactical Operational Mandate                     │
├─────────────────────┼──────────────────────────────────────────────────┤
│ Financial & Wire    │ Enforce Multi-Party Dual Control: Out-of-band    │
│ Transfer Governance │ verbal authentication via pre-shared code keys.  │
├─────────────────────┼──────────────────────────────────────────────────┤
│ Identity & Helpdesk │ Eliminate voice-based password resets; mandate   │
│ Security            │ FIDO2 hardware passkeys for all access tiering.  │
├─────────────────────┼──────────────────────────────────────────────────┤
│ Digital Media       │ Adopt C2PA Content Credentials across all        │
│ Infrastructure      │ outward-facing corporate communications/videos.  │
├─────────────────────┼──────────────────────────────────────────────────┤
│ Workforce Readiness │ Conduct realistic synthetic social engineering   │
│ & Training          │ simulations combining cloned voice and video.    │
└─────────────────────┴──────────────────────────────────────────────────┘
- Establish Out-of-Band Verification Protocols: Never allow financial transactions, bank detail adjustments, or sensitive data exports to be authorized solely via incoming phone calls or video conferences. Mandate dual-custody approval workflows: any transfer above a fixed dollar threshold must be verified through a secondary, independent communication channel using pre-shared cryptographic verification phrases.
- Harden IT Helpdesk Authentication: Threat actors use cloned employee voices to call corporate IT helpdesks, claim they lost their phone, and request an MFA reset. Helpdesk teams must be barred from resetting MFA tokens based on voice or video calls alone. Mandate in-person verification or hardware-backed challenge-response authentication.
- Deploy Enterprise Deepfake Detection Filters: Integrate real-time deepfake audio and video detection algorithms into enterprise communication software (Zoom, Teams) to analyze inbound video feeds and voice streams for synthetic anomalies during high-stakes corporate discussions.
The New Reality of Digital Perception
Deepfake technology marks a permanent turning point in human communication.
The historical link between seeing a video and knowing it represents an authentic real-world event has been severed. As neural networks become faster, more accessible, and capable of generating media with physical fidelity, synthetic media will integrate into everyday digital culture. It will power immersive film productions, revive historical figures for education, bridge language barriers, and restore voices to the vocally impaired.
Simultaneously, it demands that society construct new technological immune systems.
Navigating the synthetic media era requires moving away from naive trust. It demands cryptographic content provenance standards like C2PA, multi-layered forensic detection tools, robust enterprise verification protocols, and a healthy dose of digital skepticism.
In an age where any voice can be synthesized and any face can be rendered from noise, authenticity is no longer something we can passively assume. It is something we must mathematically verify.