 By
For years, digital privacy advice followed a familiar script: use strong passwords, enable two-factor authentication, decline non-essential cookies, and watch out for suspicious email attachments. While those security fundamentals still matter, they were designed for an era when the primary threat was a compromised account or an overt malware infection.
That defensive model is no longer enough.
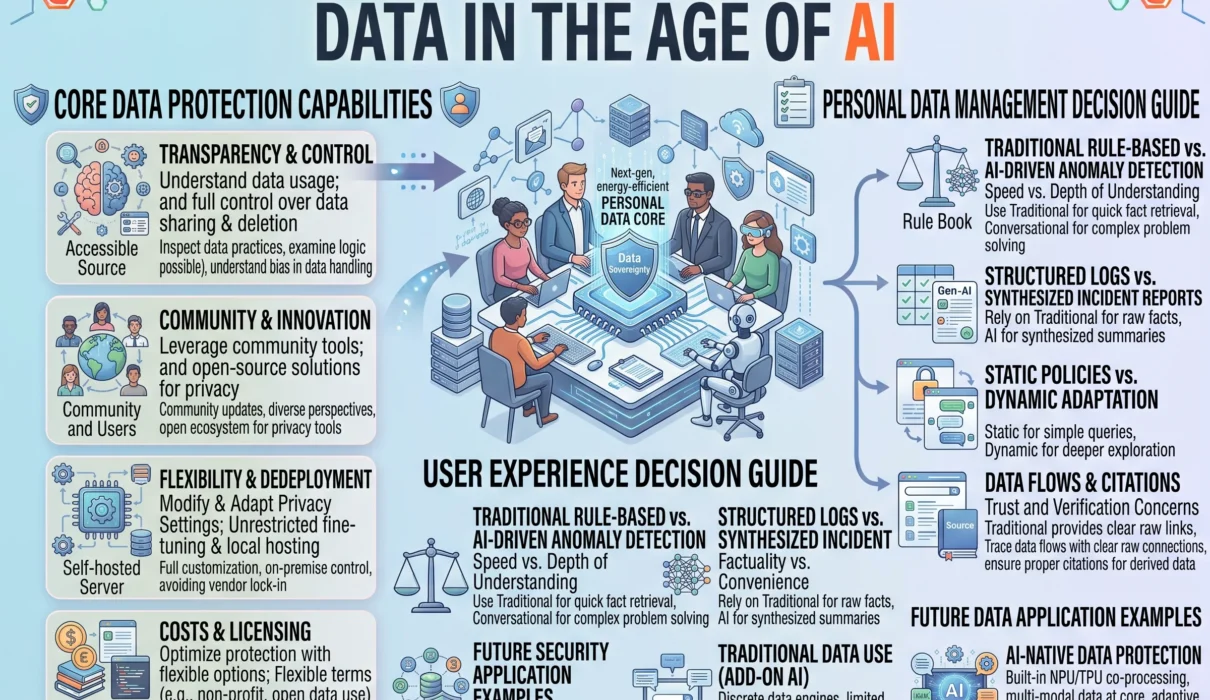
The rise of generative artificial intelligence, multimodal ambient tracking, and algorithmic data harvesting has fundamentally transformed digital surveillance. AI systems do not simply store your data; they ingest it, correlate seemingly disconnected fragments across platforms, extract behavioural patterns, infer sensitive psychological and medical traits, and use those insights to train new foundation models.
Every time you type a prompt into an AI assistant, grant a mobile app continuous background microphone access, sync your photo library to an unencrypted cloud, or browse the web with a standard browser profile, you leave digital traces that feed automated profiling engines.
Learning how to protect personal data in the AI era requires moving past basic cyber hygiene. It demands an intentional strategy designed to secure your smartphones, web browsers, generative tools, and cloud storage against automated surveillance.
                    THE MODERN DATA EXPOSURE PIPELINE

  [Traditional Telemetry]          [The AI Processing Layer]        [Downstream Risk]
  • Keystrokes & Prompts    ──►    • Ingestion for Model Training   ──► • Model Memorization
  • Sensor & Camera Access  ──►    • Cross-Platform Correlation     ──► • Synthetic Profiling
  • Unencrypted Cloud Sync  ──►    • Re-Identification Models       ──► • Algorithmic Exposure
1. The New AI Privacy Threat: Why Traditional Defenses Fall Short
To defend your digital footprint, you must understand how artificial intelligence changes the privacy equation. The primary threat to online privacy is no longer just unauthorized database breaches—it is the systematic, automated synthesis of authorized data collection.
┌────────────────────────────────────────────────────────────────────────┐
│                   CLASSICAL vs. AI PRIVACY THREATS                     │
├─────────────────────┬────────────────────┬─────────────────────────────┤
│ Dimension           │ Classical Threat   │ Modern AI Threat            │
├─────────────────────┼────────────────────┼─────────────────────────────┤
│ Core Mechanism      │ Explicit theft of  │ Automated ingestion, model  │
│                     │ static credentials │ training, and behavioral    │
│                     │ or account data    │ inference across datasets   │
├─────────────────────┼────────────────────┼─────────────────────────────┤
│ Data Handling       │ Stored in silos;   │ Aggregated into vector      │
│                     │ isolated databases │ stores; correlated across   │
│                     │                    │ unlinked touchpoints        │
├─────────────────────┼────────────────────┼─────────────────────────────┤
│ Anonymity Reality   │ Masking name/IP    │ AI cross-referencing easily │
│                     │ prevents tracking  │ re-identifies individuals   │
│                     │                    │ via linguistic/usage patterns│
├─────────────────────┼────────────────────┼─────────────────────────────┤
│ Permanence          │ Breached data can  │ Once baked into neural      │
│                     │ be rotated/deleted │ weights, extraction and     │
│                     │ from server tables │ deletion are mathematically │
│                     │                    │ complex (Machine Unlearning)│
└─────────────────────┴────────────────────┴─────────────────────────────┘
The Breakdown of Traditional Anonymization
Historically, platforms argued that stripping your name, email address, or phone number from a dataset rendered it “anonymous.”
Modern machine learning models have rendered that claim obsolete. Machine learning algorithms excel at re-identification:
- Combining public browsing patterns, location breadcrumbs, and linguistic habits allows machine learning systems to re-link “de-identified” logs to real individuals with staggering accuracy.
- Stylometric analysis can match the rhythm, vocabulary, and grammar of an anonymous forum post or AI prompt to an individual’s known writing samples across professional platforms.
Model Memorization and Data Leakage
When you submit personal details, source code, or confidential notes to consumer-facing generative platforms, those inputs are frequently ingested into future training pipelines.
Neural networks do not store information like neatly organized relational databases; they compress patterns into billions of floating-point weights. Inadvertently, models can memorize specific training sequences. Through techniques known as training data extraction attacks, adversarial researchers have demonstrated that prompting a model with specific recursive strings can cause it to regurgitate private emails, telephone numbers, and confidential text sequences that were fed into its training corpus.
2. Hardening Your Smartphone: The Pocket Surveillance Hub
Smartphones are the most intimate data-collection hardware ever created. Equipped with high-resolution cameras, directional microphones, GPS sensors, gyroscopes, and ambient light sensors, modern mobile devices maintain a continuous stream of contextual data.
                     MOBILE SENSOR CONTAINMENT MATRIX

  [App Installation] ──► [Continuous Background Tracking] ──► [Third-Party Ad Brokers]
                                   │
                                   ▼ (Hardened Privacy Settings)
  ┌────────────────────────────────────────────────────────────────────────┐
  │ 1. Revoke Background App Refresh & Precise Location Access             │
  │ 2. Enforce Micro-Permissions: "Only While Using App"                   │
  │ 3. Enable Privacy Dashboards (Monitor Camera/Mic Tunnels)              │
  │ 4. Route Outbound Traffic through Encrypted DNS / WireGuard            │
  └────────────────────────────────────────────────────────────────────────┘
To limit ambient surveillance on iOS and Android devices, apply these configuration safeguards:
1. Audit Sensor Access and Restrict Background Permissions
Apps frequently request sensor privileges that bear no functional relationship to their core utility. A calculator does not need access to your contact list; a weather utility does not require persistent background microphone permissions.
- Disable Precise Location: Most mobile platforms allow you to decouple generic geographic region from precise satellite coordinates. Except for real-time turn-by-turn navigation, toggle off “Precise Location” across all social media, commerce, and weather applications.
- Audit Sensor Permissions Quarterly: Navigate to your operating system’s Privacy & Security dashboard. Systematically review which third-party apps hold access to your Camera, Microphone, Contacts, and Local Network. Revoke permissions for any app you have not used in the past thirty days.
- Kill Background App Refresh: Prevent applications from pinging external servers and transmitting telemetry while your phone screen is off. Restrict Background App Refresh strictly to mission-critical messaging applications.
2. Strip Advertising Identifiers and Cross-App Tracking
Both major mobile operating systems feature frameworks designed to compile advertising dossiers across disparate applications.
- On iOS: Navigate to
Settings > Privacy & Security > Trackingand ensure “Allow Apps to Request to Track” is toggled off globally. This forces the operating system to return a string of zeros when third-party applications request Apple’s Identifier for Advertisers (IDFA), restricting cross-platform ad correlation. - On Android: Navigate to
Settings > Privacy > Adsand select “Delete Advertising ID.” This removes the unified hardware-linked advertising token, preventing ad networks from building persistent profiles across distinct apps.
3. Deploy Encrypted DNS at the Operating System Level
By default, every domain lookup your phone executes (every app connection, website visit, and API ping) routes through your mobile carrier’s or local Wi-Fi provider’s unencrypted Domain Name System (DNS) servers. This allows service providers to record and monetize your digital habits.
Mitigate this by configuring system-level DNS-over-HTTPS (DoH) or DNS-over-TLS (DoT):
- Install a trusted, privacy-focused encrypted DNS profile—such as NextDNS, Quad9, or Cloudflare 1.1.1.1.
- Using a platform like NextDNS allows you to block telemetry endpoints, mobile trackers, and known profiling scripts at the network layer before an app can establish an outbound connection.
3. Securing Your Browser: Closing the Door on AI Web Scraping and Trackers
Your web browser is your primary interface with the digital world—and one of the primary surfaces for corporate telemetry.
Modern tracking mechanisms have evolved far beyond basic third-party cookies. AI-powered tracking engines utilize browser fingerprinting—analyzing your unique combination of canvas rendering traits, installed system fonts, audio hardware buffering, screen resolution, and GPU shader configurations to identify and track your identity across the web even when using incognito modes.
                    THE BROWSER FINGERPRINTING VECTOR

  [User Visits Site] ──► [Fingerprinting Script Executes]
                                   │
                                   ├─► Reads Canvas 2D/WebGL Rendering Latencies
                                   ├─► Enumerate Installed System Fonts
                                   ├─► Maps Audio API Buffer Characteristics
                                   └─► Checks Screen Geometry & Hardware Concurrency
                                   │
                                   ▼
             [Unique Hardware Fingerprint: Accuracy > 99%]
             Links incognito visits directly to your real identity.
To shield your web traffic from algorithmic scraping and fingerprint profiling, build a multi-layered browser defense:
1. Transition to a Privacy-Engineered Browser Engine
Mainstream commercial browsers are developed by the world’s largest advertising conglomerates; their primary economic incentive is data harvesting. Replace corporate default browsers with platforms built around hardcoded privacy boundaries:
- Brave: Features native, rust-based shields that block trackers, cross-site cookies, and fingerprinting scripts by default without requiring third-party extensions. It employs “fingerprint randomization,” subtly altering canvas and audio rendering APIs on every session to make your browser profile look like dynamic noise.
- Firefox (Hardened Configuration): Mozilla’s open-source browser features native Total Cookie Protection, isolating cookies to the specific domain where they were created. For advanced privacy, enable
privacy.resistFingerprintingwithinabout:configor deploy a hardened configuration like Arkenfox. - Mullvad Browser / Tor Browser: Developed in collaboration with the Tor Project, Mullvad Browser strips away all identifying platform metrics, forcing your browser to present an identical fingerprint to millions of other users worldwide.
2. Deploy Essential Privacy Extensions
If you must use standard browsers, equip them with open-source extensions designed to disrupt behavioral tracking:
- uBlock Origin: The gold standard in wide-spectrum content blocking. Beyond suppressing intrusive visual advertisements, uBlock Origin prevents connections to thousands of known data brokers, telemetry nodes, and behavioral tracking scripts.
- Privacy Badger: Developed by the Electronic Frontier Foundation (EFF), this extension uses algorithmic learning to identify and block third-party trackers that evade traditional static blocklists.
3. Clear Local Storage and Enforce Cookie Isolation
Modern tracking frameworks store persistent identifying tokens inside your browser’s local HTML5 storage rather than standard cookie files. Configure your browser to clear all temporary site data, cached files, and local storage automatically every time the application closes.
4. Interacting with AI Tools: ChatGPT, Claude, and Generative Assistants
The most urgent frontier in data protection involves conversational generative assistants. Whether you use ChatGPT, Anthropic Claude, Google Gemini, or Microsoft Copilot, your interactions with these tools require deliberate privacy hygiene.
                     CONVERSATIONAL DATA GOVERNANCE

  [User Prompt / File Upload]
                │
                ▼
  ┌────────────────────────────────────────────────────────┐
  │ ZERO-DATA-EXPOSURE SANITIZATION CHECKLIST              │
  ├────────────────────────────────────────────────────────┤
  │ 1. Scrub Direct Identifiers: Names, Emails, Phone #s   │
  │ 2. Redact Internal Architecture: URLs, Secrets, Tokens │
  │ 3. Pseudonymize Entities: Replace "Acme Corp" with "X" │
  │ 4. Toggle Off Training Participation in Account Flags  │
  └──────────────────────────┬─────────────────────────────┘
                             │
                             ▼
            [Sanitized Payload Sent to Model Endpoint]
1. Opt Out of Model Training Explicitly
By default, free consumer tiers of most AI platforms treat your prompts, conversations, uploaded files, and voice recordings as free training data for their next-generation models. You must manually disable this setting across every platform you use:
- OpenAI (ChatGPT): Navigate to
Settings > Data Controlsand toggle off “Improve the model for everyone.” Alternatively, use temporary chats for sensitive inquiries, which prevents conversations from appearing in your history or feeding training pipelines. - Anthropic (Claude): Review your profile privacy settings. Anthropic does not train its commercial models on user prompts by default on paid tiers, but free consumer accounts must verify that data-sharing toggles for model improvement remain disabled.
- Google (Gemini): Access your Google Account dashboard, navigate to
Data & Privacy > Gemini Apps Activity, and turn the setting off. This stops human reviewers from reading and evaluating your conversations and halts model fine-tuning on your prompt history.
2. Apply the R-P-S (Redact, Pseudonymize, Synthesize) Rule
Never paste raw, unredacted corporate documents, customer files, or personal reflections into an external AI platform. Apply the R-P-S Rule before hitting submit:
- Redact (Direct PII): Strip out names, street addresses, Social Security numbers, dates of birth, telephone numbers, and financial account identifiers.
- Pseudonymize (Entities): If you are drafting a sensitive business contract or an email resolving a dispute, replace the actual parties with generic tokens (e.g., replace “Acme Industrial LLC” with “Company A”, and “John Doe” with “Executive X”). Once the AI generates your requested text, paste it into your local document editor and swap the real names back in locally.
- Synthesize (Code & Configs): When using AI assistants to debug source code, never include live production API keys, internal IP addresses, database connection strings, or proprietary business logic algorithms. Provide a generic, abstract reproduction of the problem instead.
3. Move Sensitive Tasks to Local, Open-Source Models
The only way to guarantee that your data is not intercepted, read, or trained upon is to run machine learning models locally on your own hardware.
With the rise of specialized Neural Processing Units (NPUs) and high-bandwidth unified memory architectures on modern laptops and desktops, running capable open-weight models locally is straightforward:
- Install open-source runtimes like Ollama, LM Studio, or Jan.ai.
- Download compact, highly optimized Small Language Models (such as Meta’s Llama 3 8B, Mistral 7B, or Microsoft’s Phi-3).
- These models run entirely offline, isolated from the internet. You can parse personal tax filings, summarize private medical journals, and process proprietary codebases with zero data egress.
5. Reclaiming Cloud Privacy: Encryption and Zero-Knowledge Architecture
The modern cloud is built on convenience, but standard cloud storage services (Google Drive, Microsoft OneDrive, Dropbox, iCloud without advanced settings) retain the cryptographic keys to your data.
This means that service operators, automated scanning algorithms, training web crawlers, and government authorities can access your files in plaintext if compelled or compromised.
STANDARD CLOUD vs. ZERO-KNOWLEDGE ENCRYPTED CLOUD

Standard Cloud Architecture:
[Your Laptop / Phone] ──(Encrypted in Transit)──► [Cloud Provider Server]
                                                         │
                                                         ├─ Provider holds the keys.
                                                         ├─ Automated AI indexing parses files.
                                                         └─ Vulnerable to insider threat & subpoenas.

Zero-Knowledge (End-to-End Encrypted) Architecture:
[Your Laptop / Phone]
        │
        ├─ Encrypted LOCALLY on device with your private key.
        ▼
[Cloud Provider Server] ──► Only hosts unreadable ciphertext blocks.
                            (Provider cannot decrypt, parse, or train on your data.)
1. Enforce Zero-Knowledge (End-to-End) Encryption
To insulate your long-term digital life from automated AI indexing, your files must be encrypted before they leave your hardware. This architectural standard is called Zero-Knowledge Encryption (or Client-Side Encryption):
- Proton Drive / Tresorit: Cloud storage platforms architected from the ground up on zero-knowledge protocols. Your files are encrypted on your local device before transmission; the cloud provider cannot decrypt your data, view your photos, or parse your documents.
- Apple Advanced Data Protection (ADP): If you use the Apple ecosystem, navigate to
Settings > [Your Name] > iCloud > Advanced Data Protectionand turn it on. By default, Apple holds the recovery keys for standard iCloud backups. Enabling ADP transitions your iCloud backups, Photos, Notes, and Voice Memos to genuine end-to-end encryption, ensuring that only your trusted devices hold the decryption keys.
2. Use Client-Side Encryption Over Existing Cloud Storage
If you rely on Google Drive or OneDrive for work or collaboration, you do not need to abandon them completely. You can layer client-side encryption on top of them using open-source tools:
- Cryptomator: A free, open-source utility that creates an encrypted virtual vault inside your existing cloud storage folder.
- Any file dropped into the Cryptomator vault is scrambled with AES-256 encryption locally on your device before your cloud provider syncs it. Your cloud provider simply sees unreadable, scrambled binary files, neutralizing automated data extraction.
6. Real-World Privacy Toolkit
To take the guesswork out of hardening your digital footprint, use this curated matrix of privacy-respecting alternatives to common consumer platforms:
┌────────────────────────────────────────────────────────────────────────┐
│                   PRIVACY-FIRST ALTERNATIVES MATRIX                    │
├───────────────────┬────────────────────┬───────────────────────────────┤
│ Everyday Tool     │ High-Exposure Tool │ Privacy-Hardened Alternative  │
├───────────────────┼────────────────────┼───────────────────────────────┤
│ Web Browser       │ Google Chrome,     │ Brave, Mullvad Browser,       │
│                   │ Microsoft Edge     │ Hardened Firefox│
├───────────────────┼────────────────────┼───────────────────────────────┤
│ Search Engine     │ Google Search,     │ DuckDuckGo, Brave Search,     │
│                   │ Bing Search        │ SearXNG (Self-hosted)│
├───────────────────┼────────────────────┼───────────────────────────────┤
│ Cloud Storage     │ Standard Dropbox,  │ Proton Drive, Tresorit,       │
│                   │ Google Drive       │ Cryptomator Vaults   │
├───────────────────┼────────────────────┼───────────────────────────────┤
│ Email Service     │ Gmail, Outlook,    │ Proton Mail, Tuta Mail        │
│                   │ Yahoo Mail         │ (Zero-Access Storage)│
├───────────────────┼────────────────────┼───────────────────────────────┤
│ Mobile Messaging  │ SMS, WhatsApp,     │ Signal Private Messenger      │
│                   │ Facebook Messenger │ (Sealed Sender Architecture)  │
├───────────────────┼────────────────────┼───────────────────────────────┤
│ AI Assistant      │ Cloud ChatGPT,     │ Local Ollama / Jan.ai,        │
│                   │ Public Gemini      │ Duck.ai, Brave Leo   │
└───────────────────┴────────────────────┴───────────────────────────────┘
7. Strategic Blueprint: Your Step-by-Step Data Protection Checklist
Achieving meaningful digital privacy does not require disconnecting from modern society or abandoning productivity tools. It requires establishing clear boundaries that minimize exposure while maintaining everyday utility.
Follow this prioritized implementation plan to harden your defenses systematically:
┌────────────────────────────────────────────────────────────────────────┐
│                   ACTIONABLE PRIVACY ROADMAP                           │
├─────────────────────┬──────────────────────────────────────────────────┤
│ Phase               │ Implementation Steps                             │
├─────────────────────┼──────────────────────────────────────────────────┤
│ Phase 1: Immediate  │ • Opt out of model training across ChatGPT,      │
│ Quick Wins          │   Claude, and Gemini account consoles.          │
│ (Under 30 Minutes)  │ • Install uBlock Origin on your browsers.       │
│                     │ • Delete Mobile Ad IDs on iOS and Android.       │
├─────────────────────┼──────────────────────────────────────────────────┤
│ Phase 2: Medium     │ • Strip unnecessary sensor permissions across    │
│ Hardening           │   mobile apps (Camera, Mic, Location).         │
│ (This Weekend)      │ • Configure encrypted DNS (NextDNS/Quad9) on     │
│                     │   your home router and mobile devices.           │
│                     │ • Enable Apple Advanced Data Protection or setup │
│                     │   Cryptomator for sensitive cloud archives.      │
├─────────────────────┼──────────────────────────────────────────────────┤
│ Phase 3: Advanced   │ • Download Ollama or LM Studio to handle local   │
│ Sovereignty         │   document analysis and code debugging.         │
│ (Ongoing Practice)  │ • Transition sensitive communication to Signal.  │
│                     │ • Migrate primary email to a zero-access provider│
│                     │   and deploy unique email aliases for accounts.  │
└─────────────────────┴──────────────────────────────────────────────────┘
1. Deploy Unique Email Aliases (Compartmentalization)
Do not use your primary personal email address across every commercial website, newsletter, and AI service. If that single address is linked to multiple leaks, data brokers can connect your activities across services into a unified behavioral profile.
Use email alias services—such as SimpleLogin, AnonAddy, or Apple Hide My Email:
- Generate a random, unique forwarding address for every new service you sign up for.
- If a vendor experiences a data breach or sells your address to marketing brokers, you can instantly deactivate that specific alias without compromising your primary inbox.
2. Treat Authentication as a Hardware Primitive
Eliminate legacy authentication pathways:
- Stop using SMS-based two-factor authentication, which remains vulnerable to SIM-swapping and AI-automated social engineering attacks.
- Adopt hardware-backed passkeys (FIDO2 / WebAuthn) or dedicated physical security keys (like YubiKeys). Passkeys are cryptographically bound to specific website domains, making it impossible for an AI-generated phishing site to steal your authentication credentials.
3. Cultivate Data Minimization as a Reflex
The most secure piece of data is the one that was never collected in the first place.
Before you fill out a form field, upload a screenshot, or answer a survey prompt, ask yourself: Is this information strictly required for this software to function? If a service asks for your birthdate when simple age verification suffices, provide false data or leave the field blank. Treat your personal data as a finite, high-value asset that you safeguard deliberately.
Taking Control of Your Digital Footprint
Artificial intelligence is not a passing trend; it is the infrastructure powering modern computing. The algorithms analyzing our world will continue to grow more capable, more pervasive, and more adept at extracting meaning from digital noise.
Protecting your personal data does not mean living off the grid or rejecting technological progress. It means refusing to be passive fuel for surveillance capitalism.
By securing your smartphones, shielding your browsers, sanitizing your prompts, and moving critical workloads to local hardware and zero-knowledge clouds, you establish digital sovereignty. You ensure that technology continues to serve as a tool that amplifies your potential—without demanding your privacy, your dignity, and your autonomy as the price of admission.